
Model APIs
ServerlessOpen modelsAccelerate Inference. Maximize efficiency.
Fast and efficient serverless inference service,
based on MangoBoost's infrastructure.
Model APIs
ServerlessOpen modelsFast and efficient serverless inference service,
based on MangoBoost's infrastructure.
Mango Inference serves leading open weight models on MangoBoost's own full stack, from DPU to server to inference software. That means faster responses and more work from every token, with no GPUs or servers to manage.
An inference engine tuned across the full stack delivers up to 2.6× higher throughput and 7.9× lower latency on the same GPUs, while keeping model quality intact.
As agent workloads grow, cache hit rate drives your bill. Our prefix cache stays alive for about 1 hour, versus 10 to 30 minutes at peers, so resumed sessions keep hitting cache.
Mango Inference runs on LLMBoost™, MangoBoost's own inference engine, on infrastructure we build ourselves. The result is higher throughput than NVIDIA B200, faster responses than peers on public inference gateways, and performance validated in MLPerf® Inference.
Up to 2.6× higher throughput and up to 7.9× lower latency than open source engines on the same GPUs, with kernels auto tuned for each model.*
Long prompts and agent sessions are served from cache, not recomputed. A single cache miss resends the whole context at full price, 5 to 10× the cost of a hit.
Speedups come from the stack, not the model. GPQA-Diamond accuracy stays at the top among providers, up to 92.9%.**
MangoBoost builds every layer Mango Inference runs on, and operates it in its own AI data center. You call an endpoint. We handle everything underneath, and your requests never pass through a third party.
MangoBoost's Full Stack Infrastructure
Mango Inference
OpenAI compatible API · API keys · usage based billing · scale to zero
Mango LLMBoost™
Inference engine tuned for every model we serve
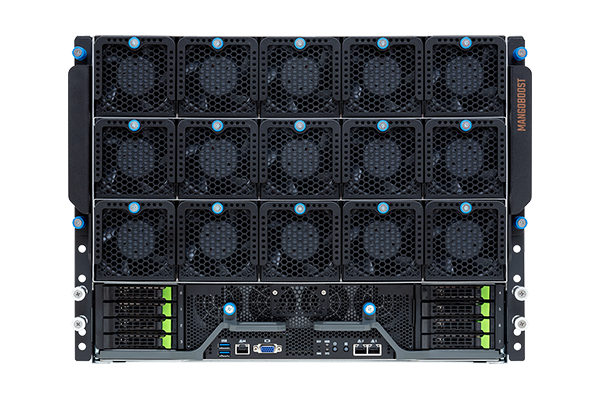
Mango Alphonso™GPU server
AMD Instinct™ MI355X/MI350P
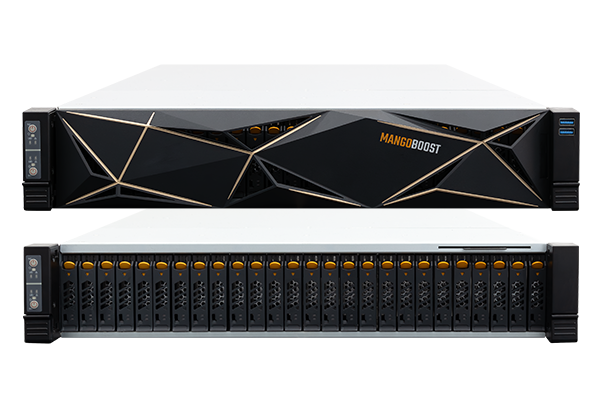
Mango Kesar™AI storage server
KV cache · model weights
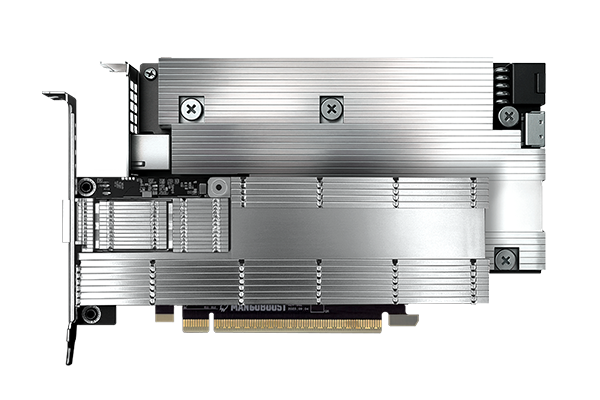
Mango BoostX™In house DPU
Network · storage offload
Mango AI Factory · MangoBoost operated AI data center
Every model is served through the same OpenAI compatible endpoint. Copy a model ID into the model field of your request to switch models.
30% off all models through Nov 11. Prices below already include the discount.
Claim your credits
DeepSeek
Available-30%USD / 1M tokens · Text → Text
Z.ai
Available-30%USD / 1M tokens · Text → Text
Z.ai
Available-30%USD / 1M tokens · Text → Text

Moonshot AI
Available-30%USD / 1M tokens · Text → Text
What teams building on Mango Inference tell us.
No infrastructure setup. Sign in, pick a model and connect your code.
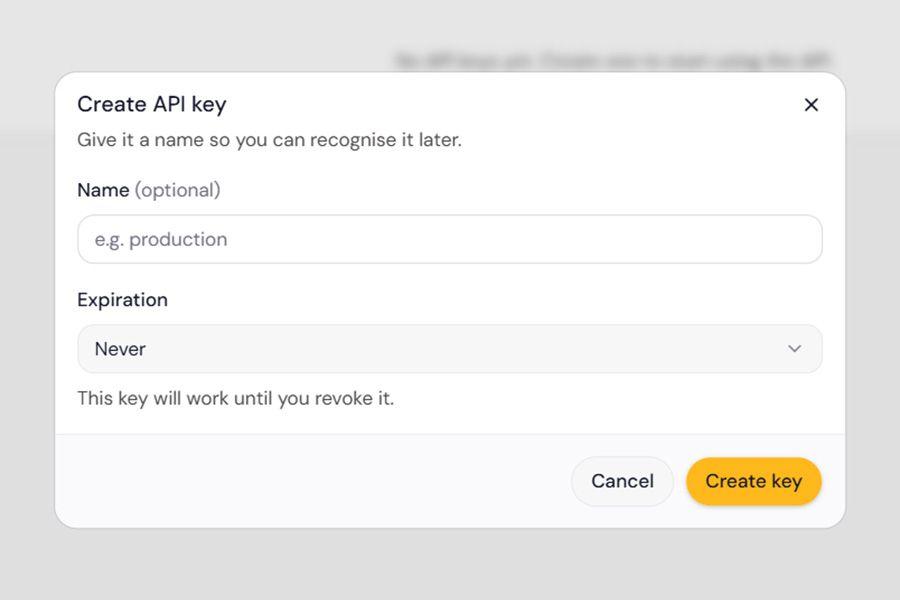
Issue an API key instantly on the Mango Inference console. No waiting.
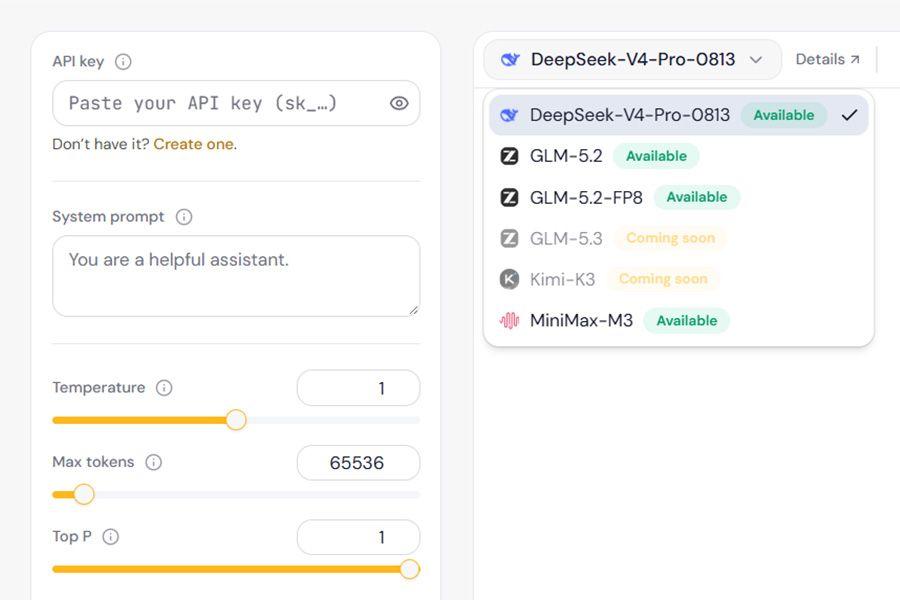
Pick an open weight model and tune parameters in the Playground to check output quality. Playground credits included.
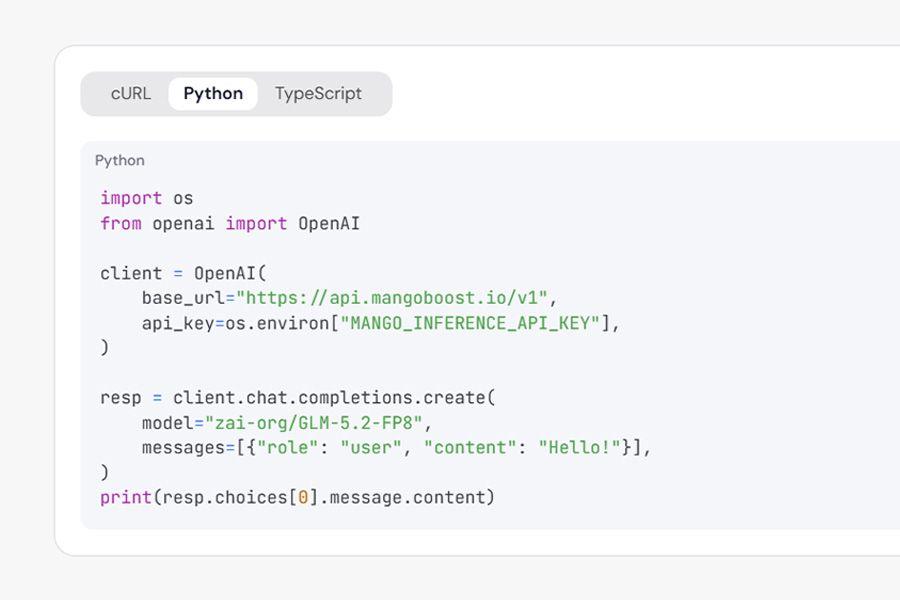
It is an OpenAI compatible endpoint. Change the base URL and model name, and your existing code just works.
Get an API key, pick an open model and point your existing code at one endpoint. Pay only for the tokens you use.