
Full-stack enterprise AI acceleration.
Run AI faster and smarter. Maximize AI performance on any hardware. Simplify AI workload deployment, scaling, and orchestration with Docker and Kubernetes.

Performance optimization.
Optimal inference performance across any workload or hardware, with zero manual tuning.


Frontier open models.
The popular open models, optimized out of the box.
Auto-tuned, turnkey inference platform.
Covers the full inference stack. Routing, serving, KV cache tiering, and storage.
Top application layer

Routing layer

Serving engine layer

Prefix tiering layer

AI ecosystem layer

AI backend storage

OS/Foundation layer

Physical hardware layer


The limit isn't the hardware. It's the software.
LLMBoost™ optimizes disaggregated prefill/decode inference on AMD Instinct™ MI300X. The result clears all 60 of NVIDIA's published H100 results on InferenceX. Verified by AMD.
Up to8.7× higher
Generation throughput
Per GPU, at equal load. Never below 2.4× from 6 to 1,229 concurrent requests.
NVIDIA H100Dynamo + TensorRT
7.9
tok/s/GPU
AMD Instinct MI300Xwith LLMBoost™
68.5
tok/s/GPU
+40%
Speed per user
174 tok/s/user, past H100's fastest.
2.5×
Lower response latency
6.0 s end to end, against H100's best.
* DeepSeek-R1-0528 FP8, 9 nodes, per GPU · H100 results as published June 25, 2026 · throughput from the 1K1K workload, per-user speed and latency from 8K1K.
Frontier Open Models. Boosted Beyond Limits.
LLMBoost™ serves and optimizes today's most popular open weights models on AMD Instinct™ GPUs (MI300X/ MI355X), delivering high token throughput and cost efficiency per token.

GLM-5.2
Z.ai (Zhipu AI)
The latest GLM generation with stronger agentic and long-context performance, served in two configurations.
GLM-5.1
Z.ai (Zhipu AI)
Z.ai's flagship general purpose model for reasoning, coding, and agents.

DeepSeek-V4
DeepSeek
An MoE model with DeepSeek Sparse Attention, serving reasoning and chat at high throughput and low cost.

Kimi K2.7
Moonshot AI
A frontier-class open model with strong tool use and long-horizon agentic capability.

MiniMax M3
MiniMax
A compact, efficient model built for coding and agentic workflows.

Qwen3.6 (27B/35B)
Alibaba Qwen
Dense mid-size models balancing quality and cost, ideal for high-volume enterprise workloads.

MiMo V2.5 Pro
Xiaomi
Xiaomi's reasoning-focused model optimized for math, code, and multi-step problem solving.

Gemma 4 31B
Google's open-weight model family, strong on multilingual chat and instruction following.
* Model availability is expanding over time and may change. All product and company names, trademarks, and logos are the property of their respective owners and are used here for identification only.
Deploy Now
Three ways to run LLMBoost™. Pick the one that fits your stack.
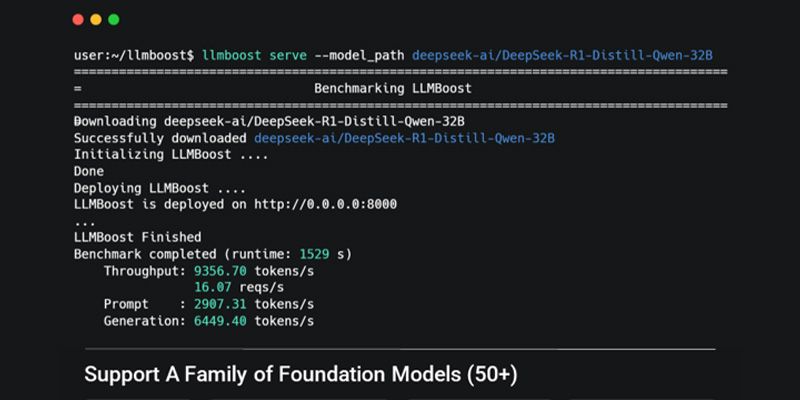
Software
Enterprise Deployment
We deploy and tune LLMBoost™ on-premise or in your own cloud. Full control of your hardware and data.
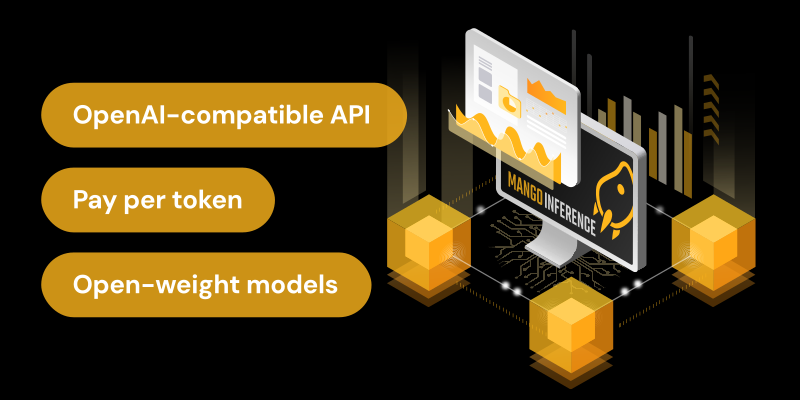
Platform
LLM-as-a-Service
Mango Inference is MangoBoost's serverless inference platform. Get an API key and start serving in minutes, no hardware needed.

System
Alphonso I GPU Server
Experience LLMBoost™ on a full-stack GPU server, pre-configured for maximum inference performance.
What workloads is it built for?
Explore the full range of workloads Mango LLMBoost™ is built to accelerate, from AI inference and training to large-scale LLM serving and beyond.
Production LLM serving
Run chatbots, copilots, and AI search at scale with consistent low latency and high throughput.
ChatbotsRAG
Enterprise fine-tuning
Train and fine-tune Llama-class models in minutes, not days. Built-in checkpointing included.
LoRALlama
Multi-modal & reasoning
Accelerate vision-language and reasoning models with up to 43× faster throughput on Qwen2.5 and 520× faster TTFT on DeepSeek-R1.
QwenDeepSeek
Hybrid infrastructure
Deploy the same stack on-prem, in the cloud, or across mixed AMD GPUs and other NPUs with no vendor lock-in and no rewrites.
On-premAMD/NPUs
Latest from MangoBoost.
Benchmark milestones, engineering deep-dives and company announcements.
First-ever Multi-Region Heterogeneous Inference: MangoBoost Sets New Standards for Global AI Scaling in MLPerf Inference v6.0
MangoBoost
Learn more
MangoBoost Pushes AI Scalability in MLPerf Training v5.1: First-Ever Multi-Node MI325X Results Highlight AMD's Scaling Capabilities
MangoBoost
Learn more

Dell spotlighted MangoBoost’s LLMBoost™ for MLPerf Inference v5.1
Dell Technologies
Learn more
Pioneering Multinode Heterogeneous Inference: MangoBoost and AMD, in Collaboration with OEM Partners, Sets Record Llama2-70B Performance in MLPerf Inference v5.1
MangoBoost
Learn more

How Supermicro/AMD servers boost AI performance with MangoBoost
Performance Intensive Computing
Learn more

Supermicro GPU Servers With MangoBoost LLMBoost™ AI Enterprise Software : Unlocking the full potential of AMD Instinct™ GPUS
Supermicro
Learn more
Need a Boost?
Our team is at the ready to create a customized plan for you to optimize and scale your business.